Distilling a frontier research agent into a 9B model
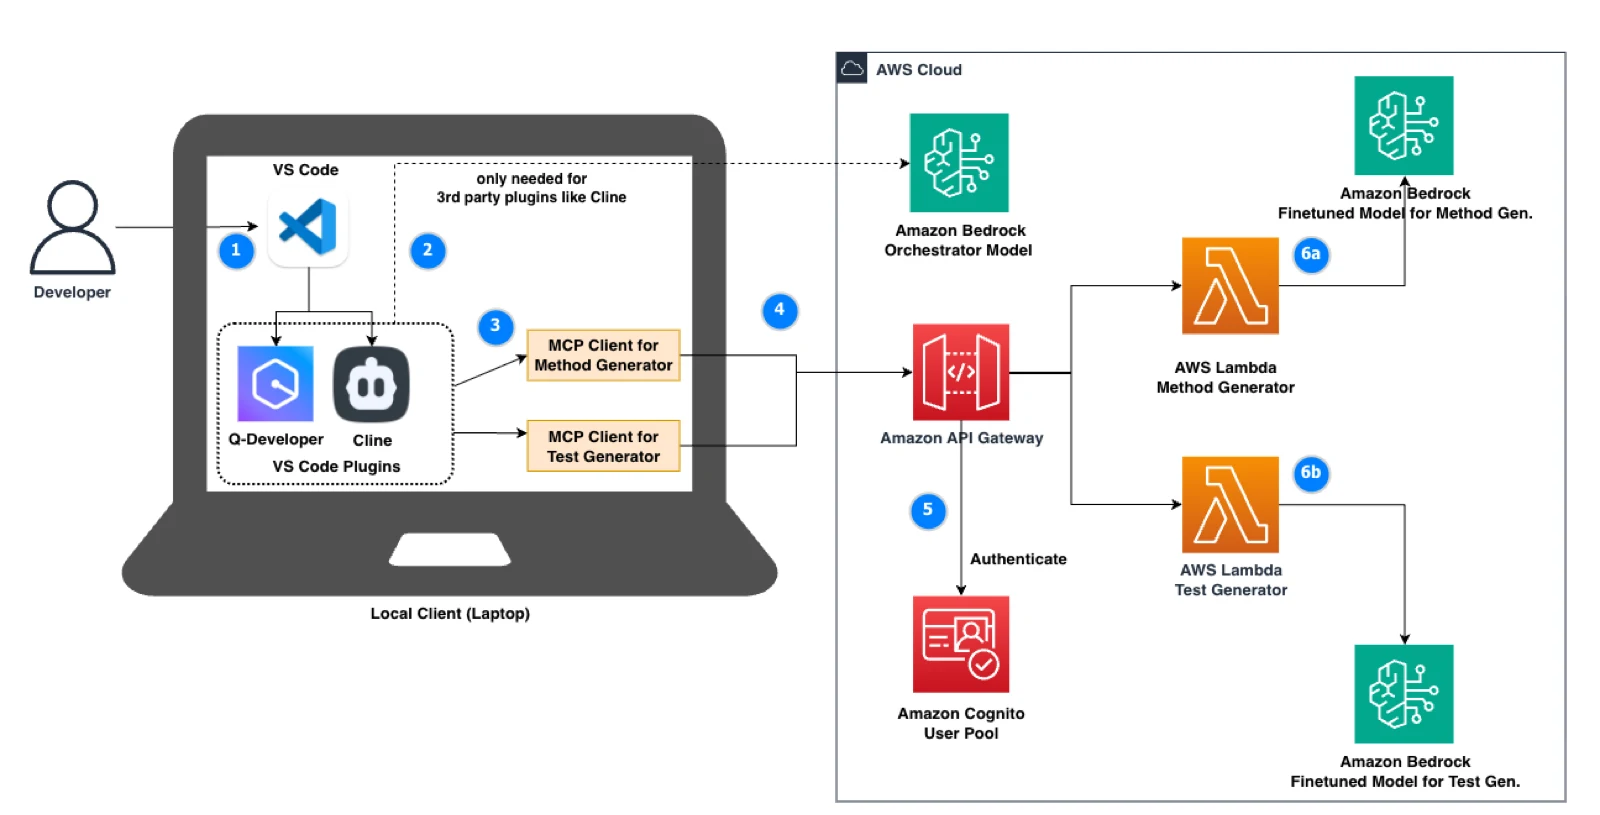
Read the full post on Builder CenterPart I built a research agent on Amazon Bedrock AgentCore that plans a report, searches across more than ten connectors, and writes with inline citations. On a frontier model it gets expensive: one question takes 20 to 30 tool calls, and across 1,833 real runs the median episode was about 26,000 tokens, two thirds of them tool output. Part II adds a pipeline to the open-source repo that trains a small open model to do the same job.
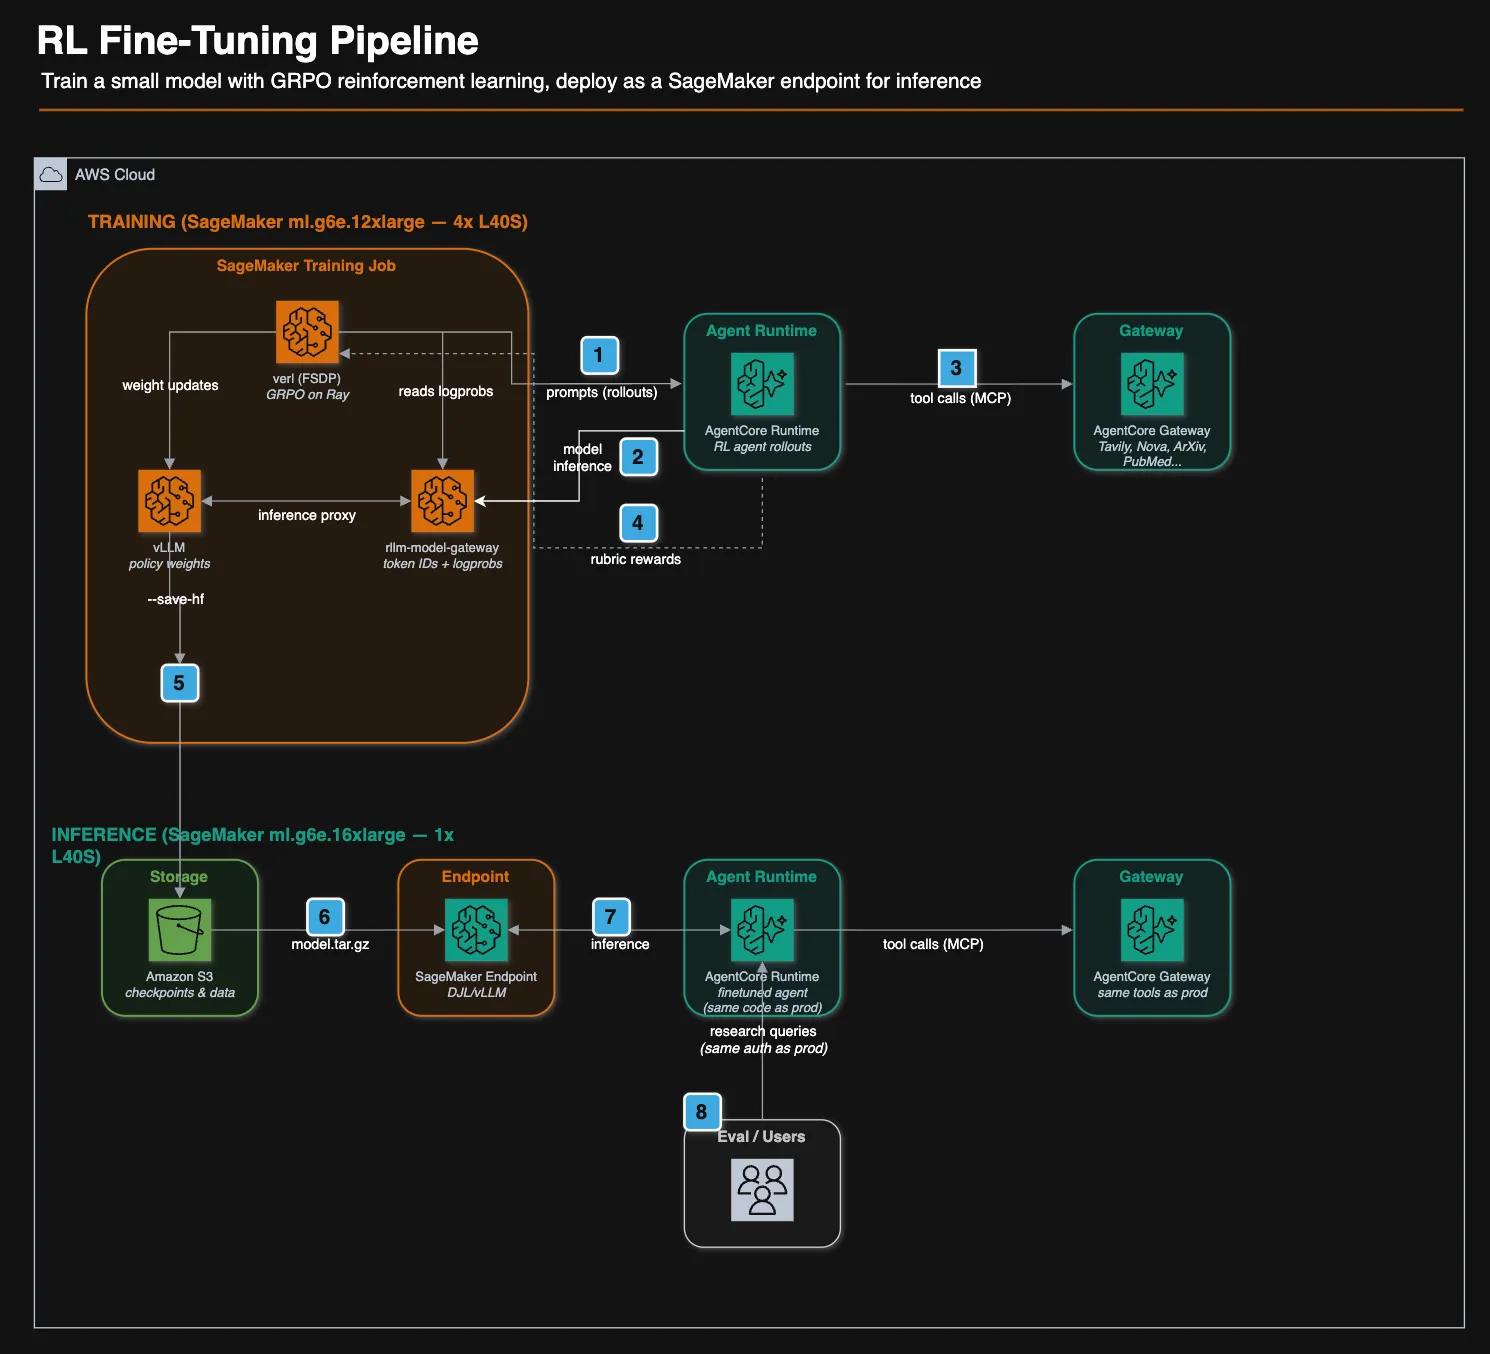
It runs in two stages. First, the production agent answers a set of research questions, and a student is fine-tuned on the recorded trajectories with LoRA, masking tool outputs from the loss so it doesn't learn to invent search results. Then GRPO on the AgentCore RL Toolkit refines it against the same agent and tools used in production. The reward is mostly an LLM-judge rubric, plus checks that every cited URL actually came from a tool and that the format is right.
With Qwen3.5-9B as the student, SFT lifted the score on 98 held-out questions from 0.538 to 0.744, level with the frontier teacher at 0.743, and citation validity from 0.299 to 0.953. GRPO added a bit more, reaching 0.782 after 150 steps, but by step 200 it had over-optimized and fell below SFT while the training reward kept climbing. The main lessons came from silent failures: chat templates missing the markers TRL needs to mask tool outputs, a default context window that truncated 86% of episodes, and a reward bug that gave full credit for invented URLs.