Home
WorkBlogTalksPapersAbout
Nikita Kozodoi

Blog

29Posts
Nikita Kozodoi

LLMs

7Posts
Source:
Tag:
AllGenAIEvaluationAgentsDeep LearningLLMsKaggleClassical MLHealthcarePyTorchComputer VisionIDPPythonAutomotiveFine-TuningMLOpsRAGResponsible AI
7 posts

Posts

Builder Center2026

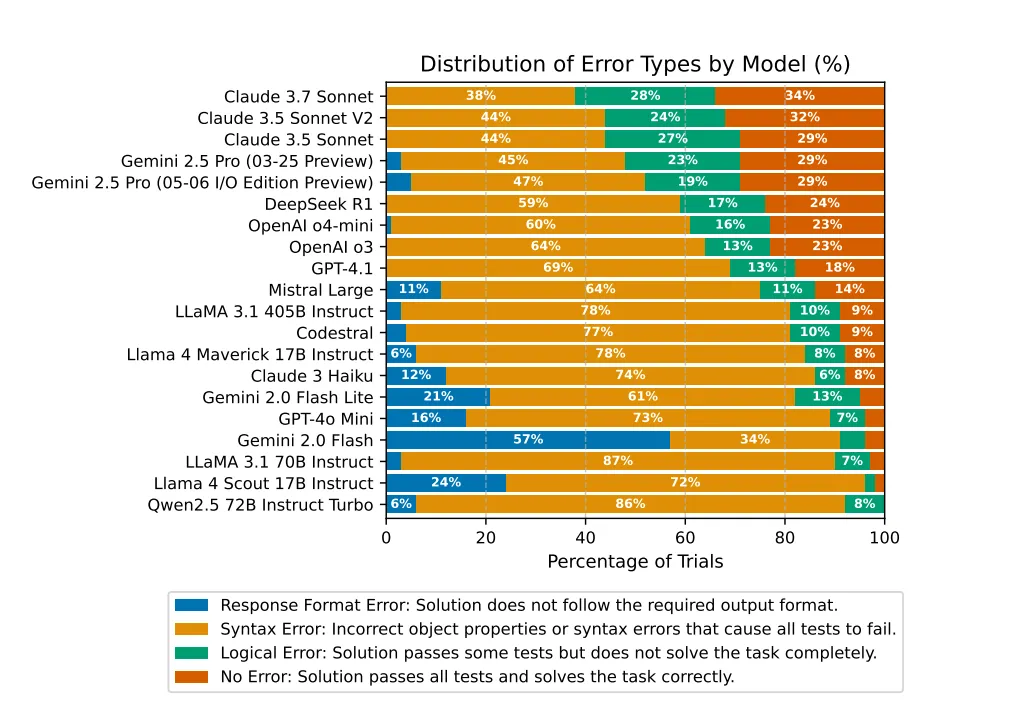
SWE-InfraBench + Kiro: What Happens When a Coding Agent Tackles IaC?

Language models solved only 34% of SWE-InfraBench's infrastructure-as-code tasks in one attempt. We ran Kiro over all 100 and found that a full agent loop with Sonnet 5 reaches 82%, with partially correct answers converging once the agent can re-run the tests itself.
GenAIAgentsEvaluation
AWS Blog2026

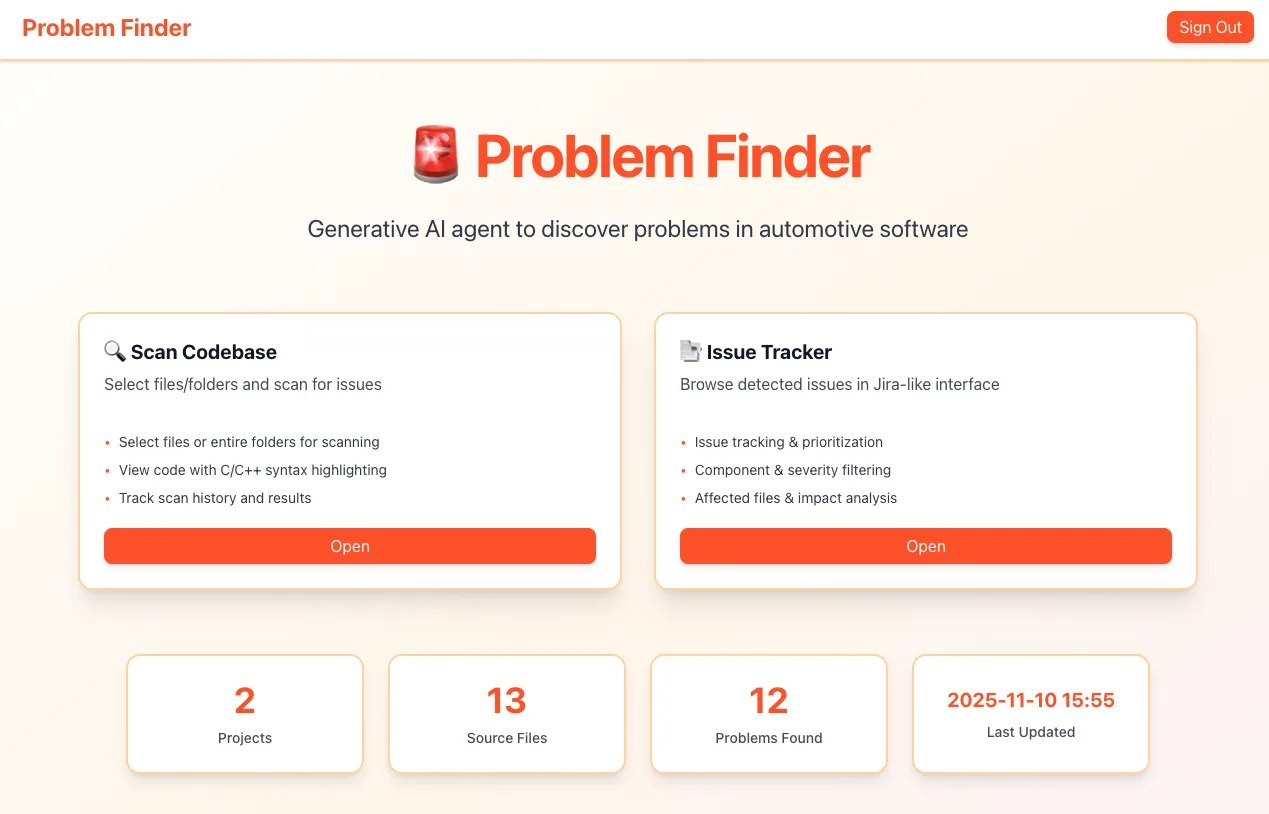
AUMOVIO Improves Quality of Automotive Software at Scale Using Multi-Agent AI on Amazon Bedrock

Defects that clear compilers, static analyzers and code review still surface during vehicle integration testing, the most expensive place to find them. We built a multi-agent system that detected 30+ high-priority findings on production code.

GenAIAgentsAutomotive
Builder Center2026

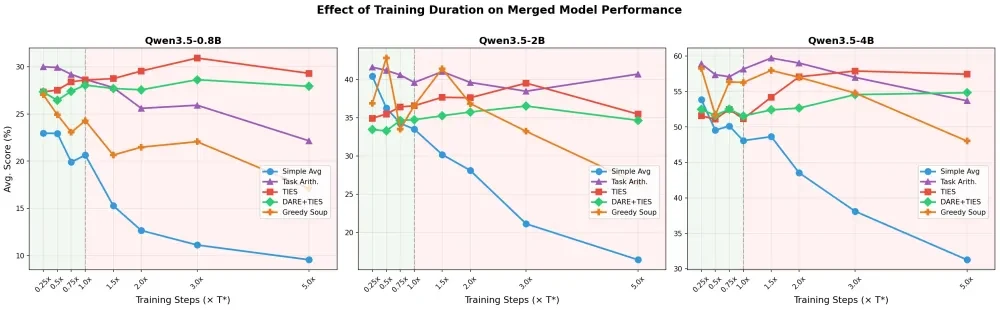
Are We Merging the Right Models?

We benchmark Task Arithmetic, TIES, DARE, and Model Soups for merging Qwen3.5 experts across five domains. The best expert training duration turns out to depend on the merging method, with sparsification-based methods peaking well past the validation optimum.

GenAILLMsFine-Tuning
Builder Center2026

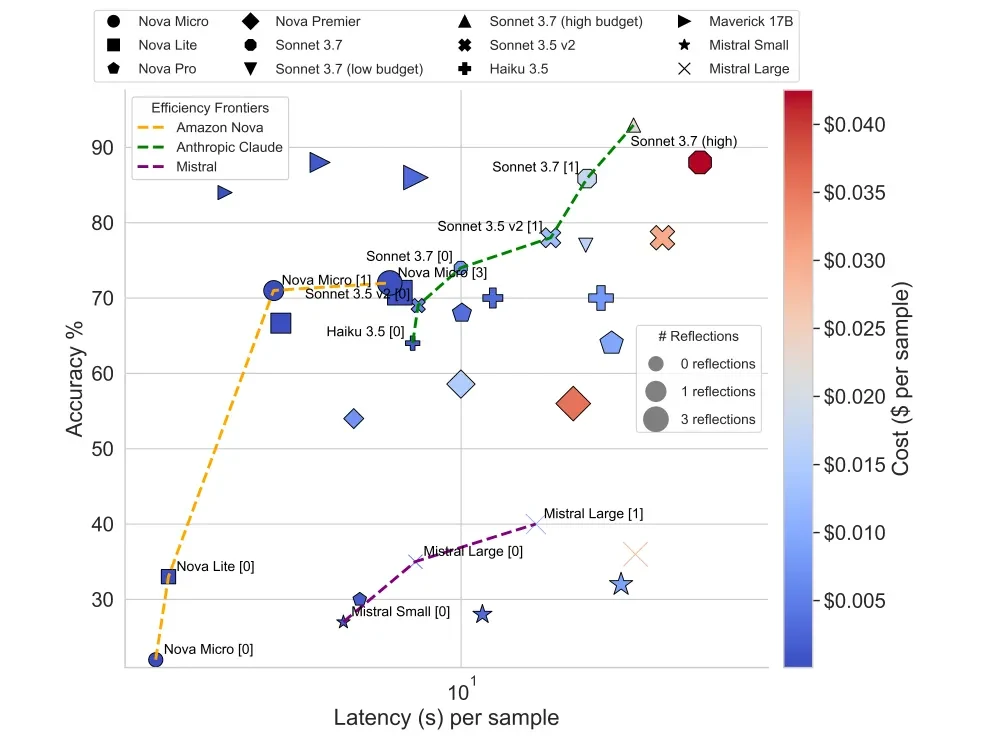
Boost Your LLM Performance on Amazon Bedrock with Self-Reflection

Self-reflection lets a model critique and revise its own output before returning it. We apply it at inference time on Amazon Bedrock and measure the accuracy gain against the added cost and latency across reflection depths.

GenAILLMsEvaluation
AWS Blog2026

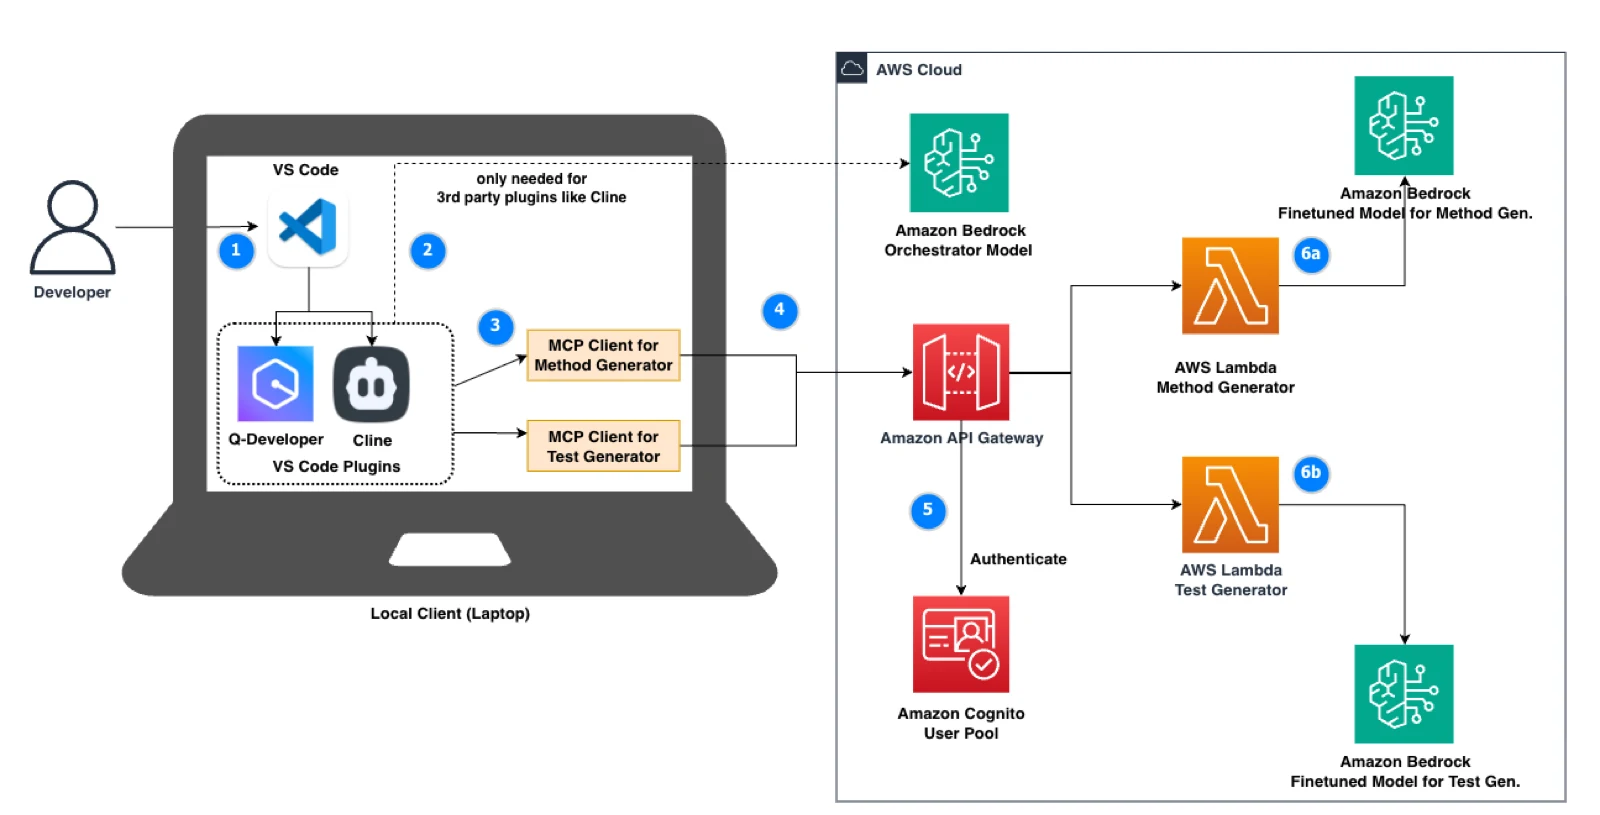
AUMOVIO Boosts Software Development with an Agentic Coding Assistant Powered by Amazon Bedrock

We paired a fine-tuned Qwen3-32B with Claude Sonnet orchestration over Amazon Bedrock and MCP to build a multi-model coding assistant. Fine-tuning on 7,000 annotated functions cut C++ architecture compliance violations to 0.02 against generic models.

GenAILLMsFine-Tuning
AWS Blog2025

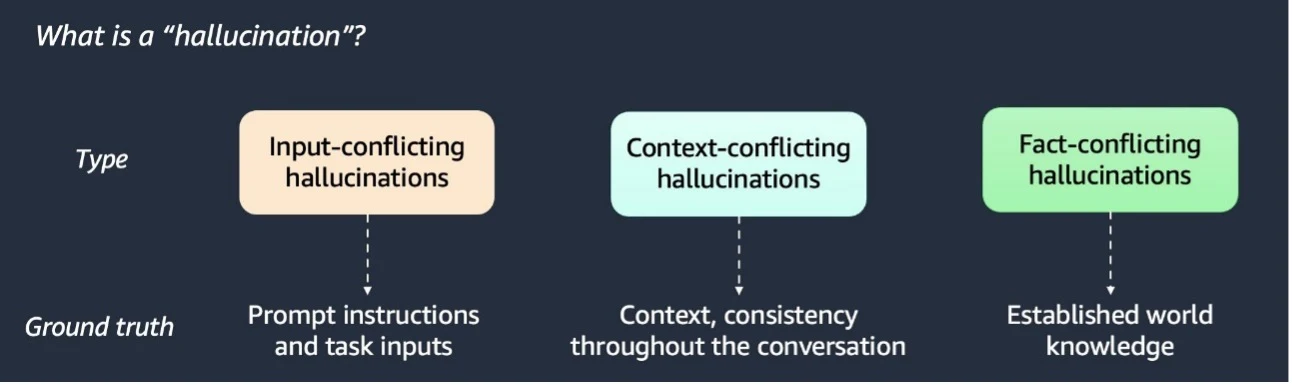
Detect Hallucinations for RAG-Based Systems

RAG systems still answer confidently when the retrieved context does not support the answer. We add a detection layer that flags those cases, comparing methods such as LLM-as-judge and semantic similarity on accuracy against cost.

GenAILLMsRAG
AWS Blog2023

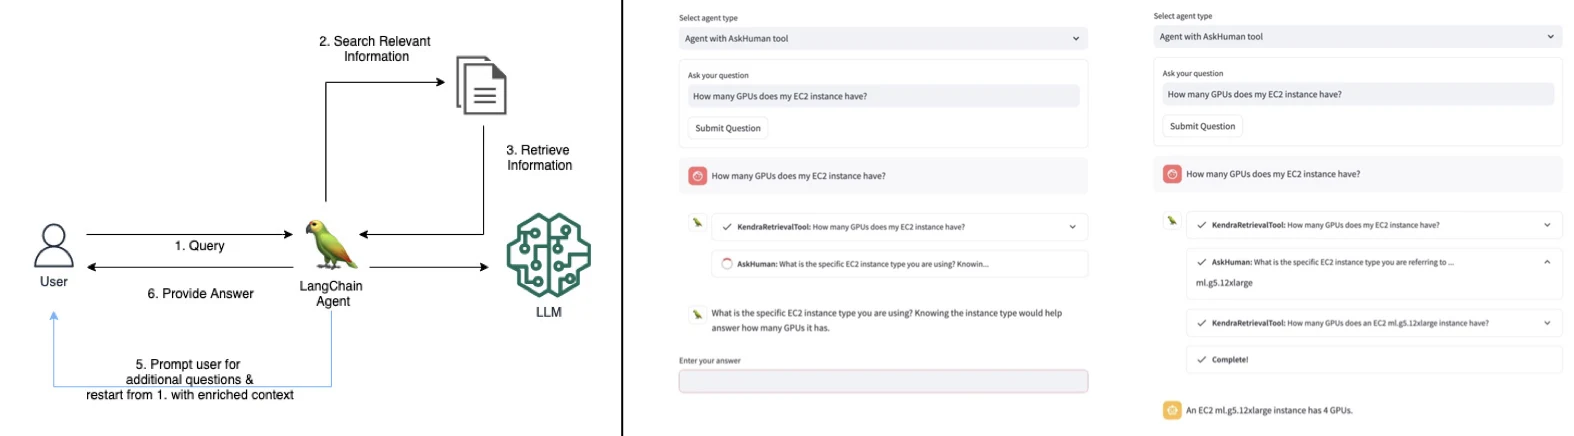
Improve LLM Responses in RAG Use Cases by Interacting with the User

When retrieval returns a weak answer, most RAG systems reply anyway. We add a clarification tool so the system asks a follow-up question instead, combining Amazon Kendra retrieval, LangChain orchestration, and Amazon Bedrock.

GenAILLMsRAG

Pages

  • Work
  • Blog
  • Talks
  • Papers
  • About

Social

  • LinkedIn
  • GitHub
  • Google Scholar
  • X / Twitter
  • Instagram

Contact

  • n.kozodoi@icloud.com
  • Buy me a coffee
  • Download CV
  • RSS feed
  • Berlin, Germany

© 2026 Nikita Kozodoi. All opinions are my own.