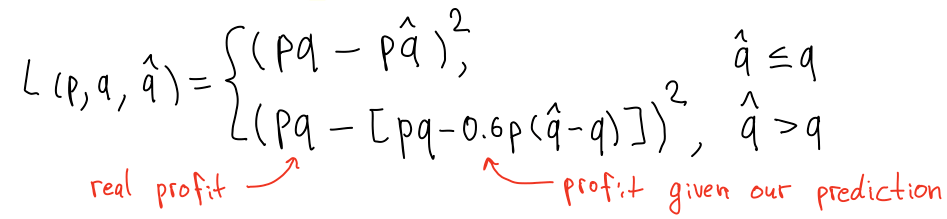
Home
WorkBlogTalksPapersAbout
Nikita Kozodoi

Blog

29Posts
Nikita Kozodoi

Evaluation

8Posts
Source:
Tag:
AllGenAIEvaluationAgentsDeep LearningLLMsKaggleClassical MLHealthcarePyTorchComputer VisionIDPPythonAutomotiveFine-TuningMLOpsRAGResponsible AI
8 posts

Posts

Builder Center2026

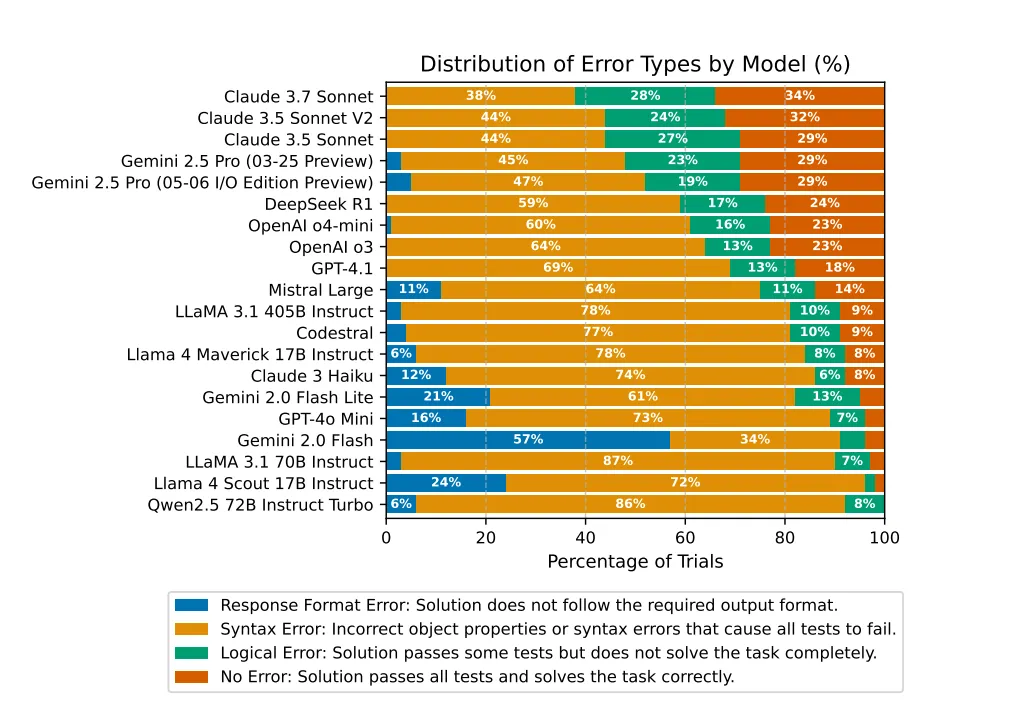
SWE-InfraBench + Kiro: What Happens When a Coding Agent Tackles IaC?

Language models solved only 34% of SWE-InfraBench's infrastructure-as-code tasks in one attempt. We ran Kiro over all 100 and found that a full agent loop with Sonnet 5 reaches 82%, with partially correct answers converging once the agent can re-run the tests itself.
GenAIAgentsEvaluation
Builder Center2026

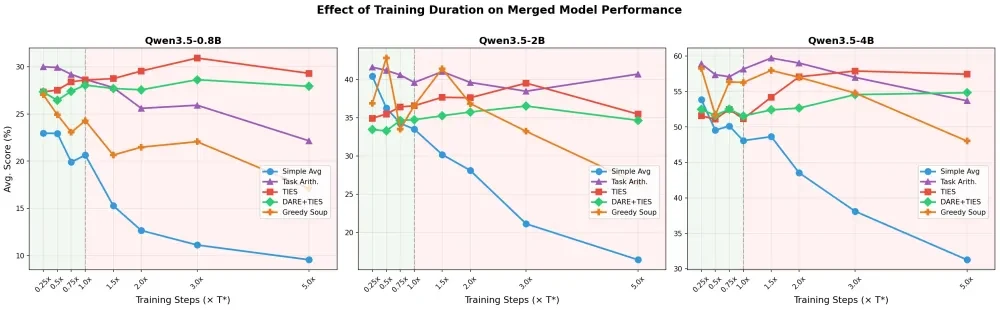
Are We Merging the Right Models?

We benchmark Task Arithmetic, TIES, DARE, and Model Soups for merging Qwen3.5 experts across five domains. The best expert training duration turns out to depend on the merging method, with sparsification-based methods peaking well past the validation optimum.

GenAILLMsFine-Tuning
Builder Center2026

Boost Your LLM Performance on Amazon Bedrock with Self-Reflection

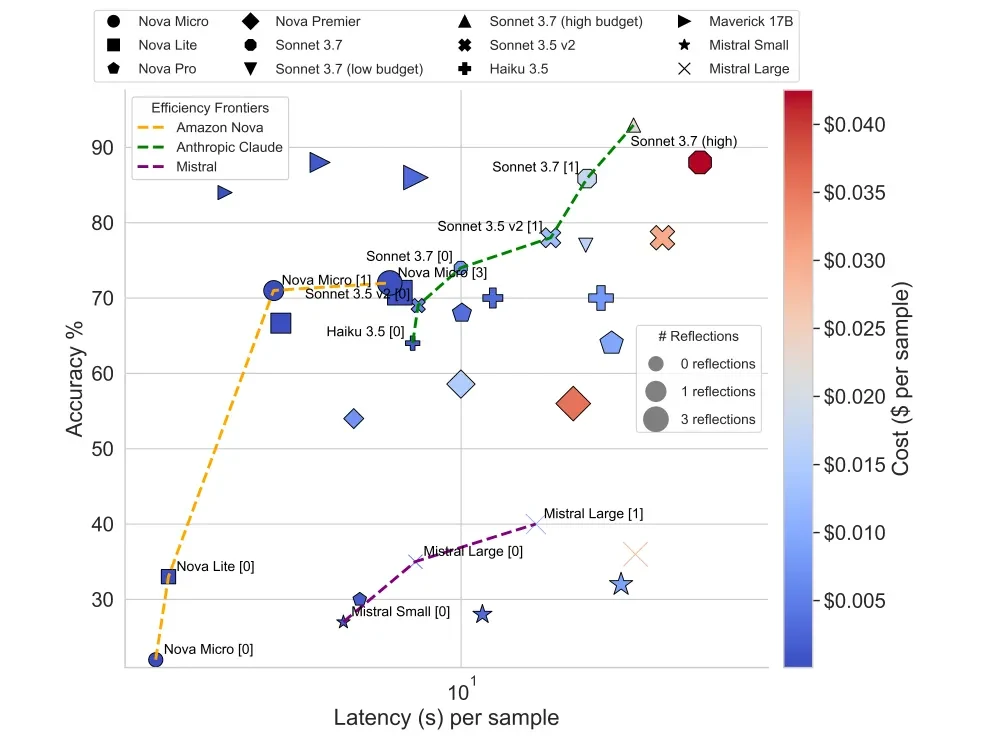
Self-reflection lets a model critique and revise its own output before returning it. We apply it at inference time on Amazon Bedrock and measure the accuracy gain against the added cost and latency across reflection depths.

GenAILLMsEvaluation
AWS Blog2026

Scaling Medical Content Review at Flo Health Using Amazon Bedrock

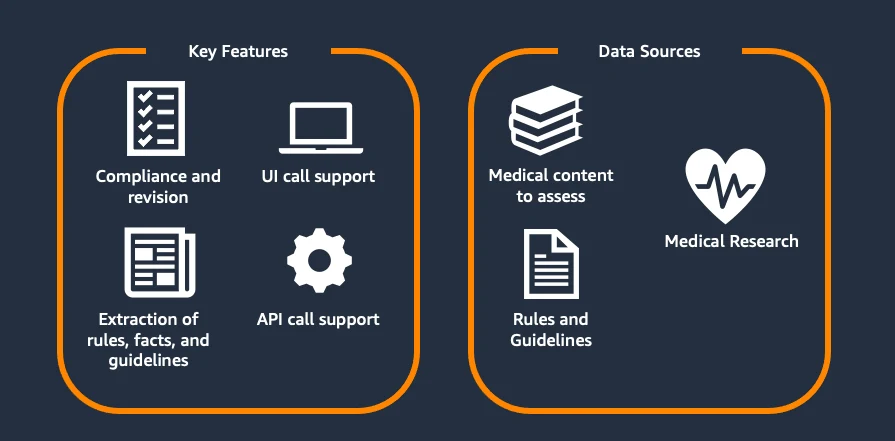
We built MACROS, a system on Amazon Bedrock with Lambda and Step Functions that reviews medical articles against guidelines and proposes revisions. The proof of concept reached 80% accuracy and over 90% recall, cutting per-guideline review from hours to minutes.

GenAIHealthcareEvaluation
AWS Blog2025

Detect Hallucinations for RAG-Based Systems

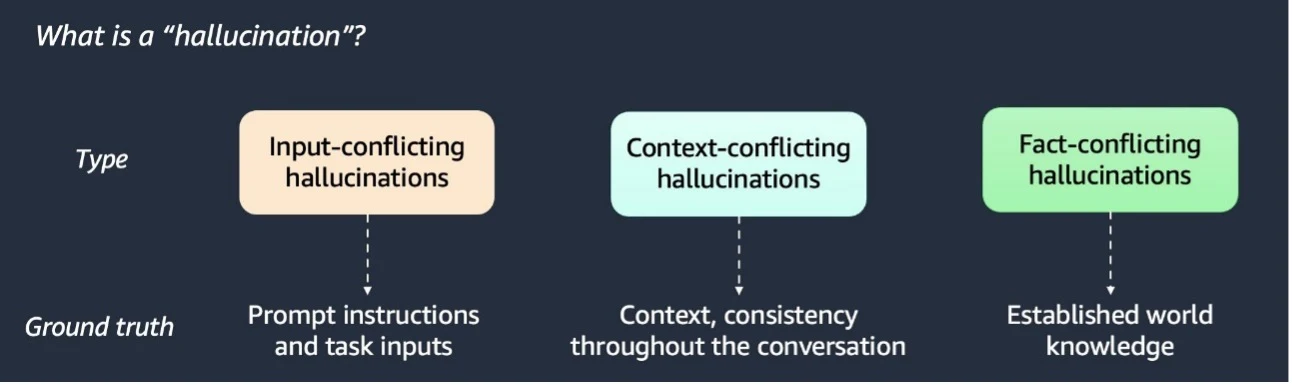
RAG systems still answer confidently when the retrieved context does not support the answer. We add a detection layer that flags those cases, comparing methods such as LLM-as-judge and semantic similarity on accuracy against cost.

GenAILLMsRAG
Self-published2021

Test-Time Augmentation for Tabular Data

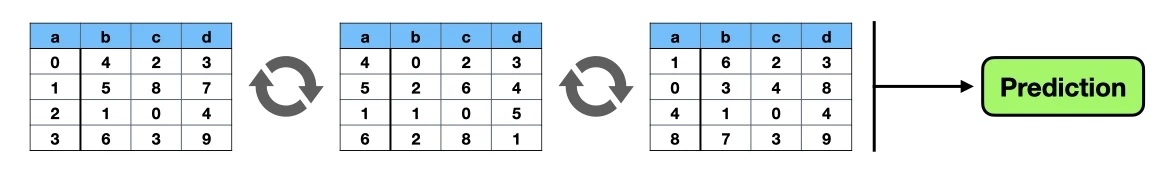
This post adapts test-time augmentation, a computer vision technique, to tabular data. We benchmark strategies for numeric and categorical features and measure how much accuracy they actually buy at inference.

PythonClassical MLKaggle
Self-published2020

Profit-Driven Demand Forecasting

We forecast retail demand with gradient boosted trees in our Data Mining Cup 2020 solution. Optimizing a profit-based objective rather than plain forecast error aligns the model with the underlying inventory cost and revenue trade-offs.

Classical MLKaggleEvaluation
Self-published2020

Algorithmic Fairness in R

This post introduces the fairness R package for computing and visualizing algorithmic fairness metrics. We walk through demographic parity, proportional parity, and equalized odds, and show how the three diverge on the very same classifier.

Responsible AIClassical MLEvaluation

Pages

  • Work
  • Blog
  • Talks
  • Papers
  • About

Social

  • LinkedIn
  • GitHub
  • Google Scholar
  • X / Twitter
  • Instagram

Contact

  • n.kozodoi@icloud.com
  • Buy me a coffee
  • Download CV
  • RSS feed
  • Berlin, Germany

© 2026 Nikita Kozodoi. All opinions are my own.